Backlist analysis using AI: Identifying and systematically exploiting potential
Management consultant Martina Steinröder explains, in five steps, how to analyse your backlist efficiently.
Published: 18 August 2026 | Photo: AI-generated, Magnific
Publishers have access to extensive data on their published titles, but rarely make systematic use of it. Generative AI significantly lowers the barrier to regular analysis. Martina Steinröder demonstrates how this works in practice in the webinar from the Digital Publishing Report’s ‘How-to’ series.
Extensive backlists harbour untapped potential. That is, in fact, a truism. In day-to-day work, however, there is neither the time nor the impetus for a systematic analysis. This is precisely where Martina Steinröder, founder of Steinröder Publishing Consulting and an expert in digital transformation, in the webinar from the Digital Publishing Report’s ‘How-to’ series to.
The situation is similar at most publishing houses: data on titles that have already been published is available, but is perhaps only used once a year for programme planning. For the rest of the year, this data remains unused.
Generative AI can change all that. It allows back-list data to be analysed regularly, quickly and with a manageable amount of effort. The webinar guides you through the process in five steps.
Clarify the question
The most important step comes before the actual analysis. The following need to be clarified: What questions is the analysis intended to answer, and which key figures are required for this?
Typical questions include: Which titles are hits and which are flops? How are turnover and sales figures trending, ideally over a five-year period? How profitable are individual titles, and what are the contribution margins? Which programme segments are driving the bottom line? And where are there gaps in the target audience coverage?
Only once the question has been formulated are the required data entered into the analysis table. This sequence saves a considerable amount of time later on.
Creating a clean data set
The basis of any AI-supported analysis is a neatly structured Excel spreadsheet: a cross-tabulation with no blank rows, no subtotals and no formatting inconsistencies. Unambiguous column headings are essential, and the data types within a column must be consistent. Number fields must contain numerals, not currency formats; dates must follow a standard format. Each cell must contain exactly one piece of information.
Free-text fields, such as programme segments, must be labelled consistently throughout. If you write ‘Internal Medicine’ in one instance and ‘IM’ in another, this will result in two segments being generated in the analysis instead of one. Abbreviations are permitted, but must always be used consistently.
The table should contain only the data that is actually required. Missing values should not be left blank, but should be marked consistently, for example with ‘n/a’. A backbone field is required to ensure the unambiguous identification of titles. The ISBN is not suitable for this purpose, as it changes with each edition; a combined field comprising the author’s name and the title, written in a standardised format, has proved effective.
It is also crucial that all the key figures to be analysed are already calculated and entered in the spreadsheet. Contribution margins and other derived figures are calculated deterministically in Excel and are not estimated by the AI. The AI is intended to process and categorise the figures, not to perform the calculations.
Analysing figures
Once the data set is in order, the actual analysis begins. There are two ways to analyse the figures: a report in the chat or an interactive dashboard.
Virtually any standard AI model is suitable for generating a report in a chat. The data is uploaded, the questions are asked, and the result is output as a report. The key lies in the prompting: specify the role, clearly describe the objective and task, and explicitly state that the model must work exclusively with the existing values and must not add anything or make any estimates.
The following output format has proved effective: a management summary, followed by a section for each key performance indicator, and finally a section on assumptions and data gaps. This ensures that the distinction between calculated values and interpretation remains clear. The AI should highlight any missing data, rather than simply ignoring it.
An interactive dashboard provides an even clearer picture. This is currently best achieved using Claude, Gemini or Codex from OpenAI. In Claude, the dashboard can be used directly as an ‘artefact’; in all three systems, the file can alternatively be downloaded and opened in a browser. Such a dashboard provides quick and visually appealing overviews of, for example, programme areas, top-flop lists, ABC analyses, forecasts and stock alerts.
Recognising patterns
The second, and even more interesting, use case is pattern recognition. This is where generative AI really comes into its own.
At portfolio level, this enables us to answer questions such as: Are there any concentration risks? What is the financial performance in the individual subject areas? How are individual series performing? Where are there gaps or areas for expansion? How up to date is the programme?
The title level is just as telling: Does a new edition make sense? Which titles should be discontinued, and which should be revived? Are there any stock risks? Are there any outliers in terms of profit margins?
It is important to note the limitation: the analysis relates exclusively to the available, valid backlist data. The market as a whole is not taken into account; for example, market gaps cannot be identified on this basis.
Here, too, the prompt determines the quality. A combination of approaches is advisable: on the one hand, clearly formulated questions, e.g. on series performance, new runs and stock risk; on the other hand, an explicit request to identify any anomalies that were not specifically asked about but are relevant to programme and title planning. It is precisely at this point that AI often provides new perspectives.
Draw conclusions
In the final step, conclusions and recommendations for action are drawn. This should be done in a new chat so that the results are not skewed by the previous analysis. The recommendations can then be exported directly as a Word document.
This results in a systematic, valid analysis of the backlist, with clearly derived recommendations for action.
Conclusion
AI makes backlist analysis quicker and clearer, and enables it to be carried out on a regular basis. Its particular strength lies in pattern recognition.
There are three prerequisites: clarity about which questions are to be answered; the careful preparation of all key figures; and a willingness to allow the AI to contextualise the data and identify patterns, rather than simply letting it perform calculations. AI remains a tool; quality control and the final interpretation are the responsibility of the users.
The effort involved is manageable. And the approach can be applied not only to backlist analyses, but to virtually any structured dataset within the publishing house.
The webinar will demonstrate the individual steps using specific examples, from preparing the Excel spreadsheet through to the prompts and the finished dashboard.
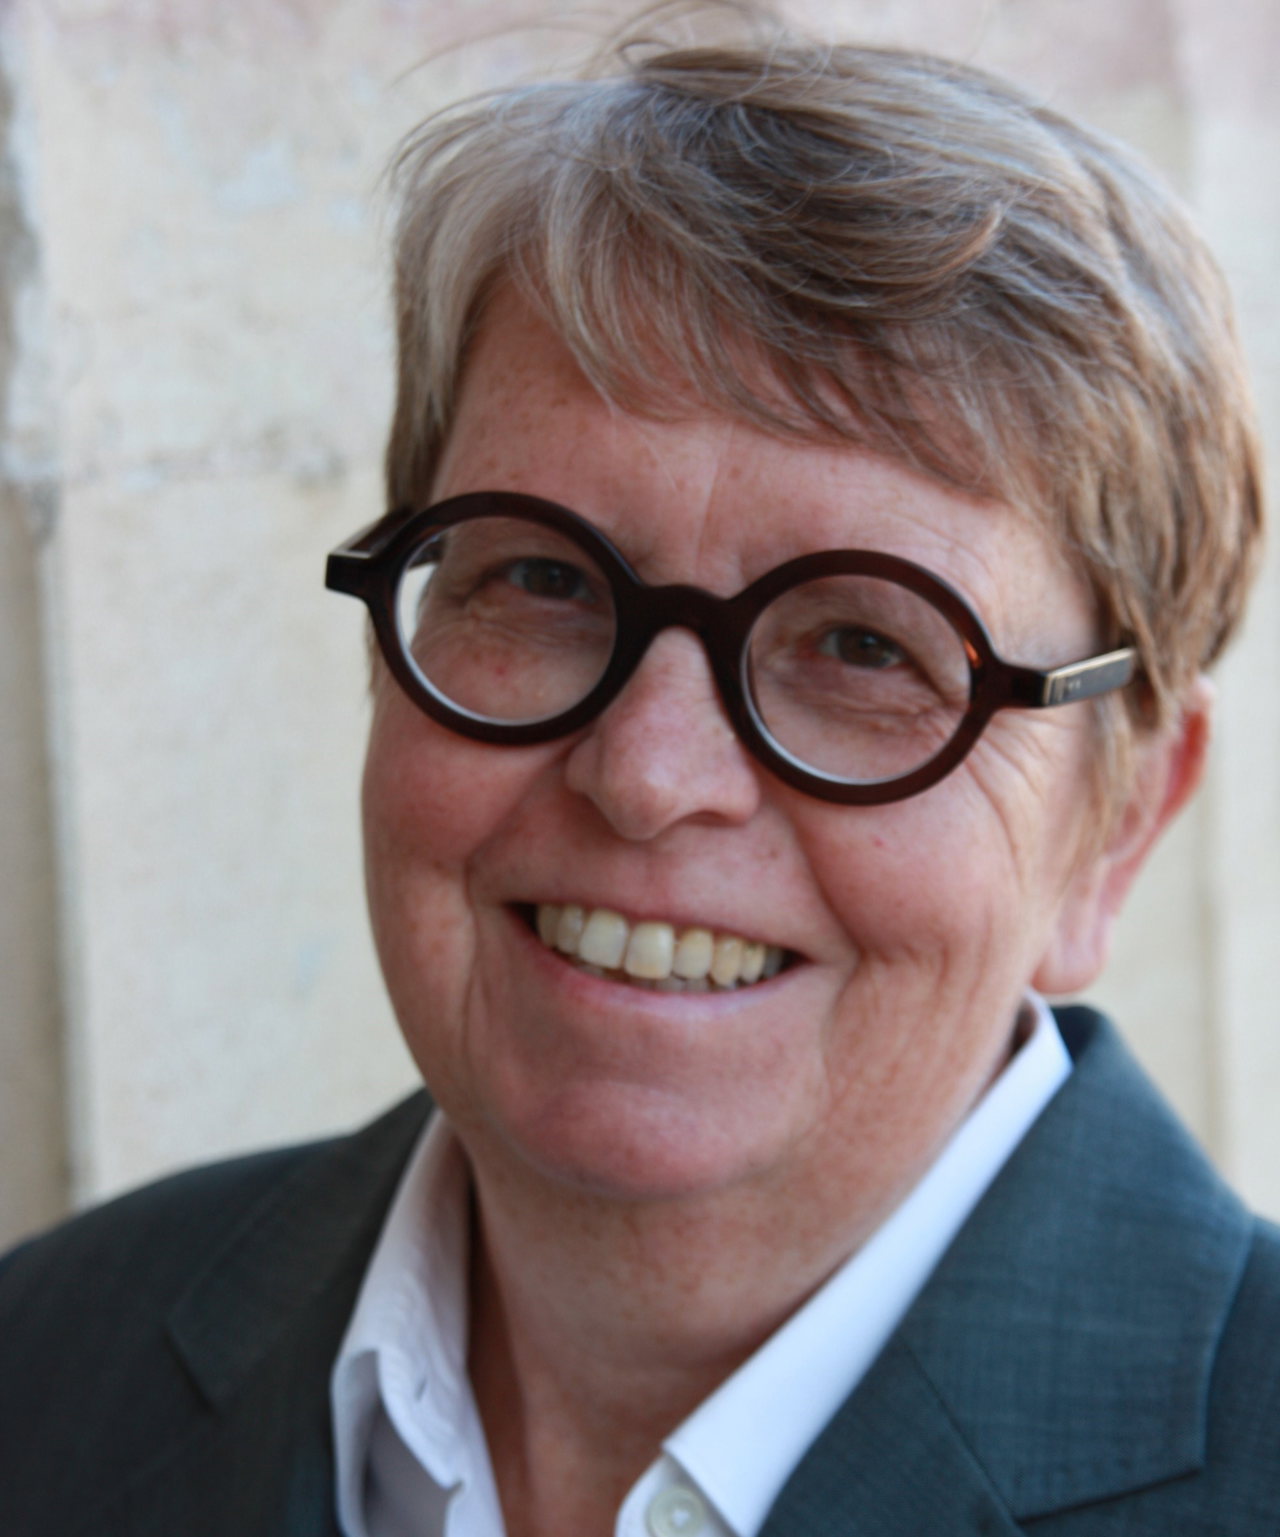
Martina Steinröder (LinkedIn) is the founder of Steinröder Publishing Consulting and an expert in digital transformation. She advises companies on the strategic design and development of digital offerings and brings extensive experience from the media industry to the role.